Goodfire’s “already clean” hypothesis needs a falsifiable neuron explanation
Nick Cammarata argues that some apparent neuron mixtures reflect shared structure. The useful research response is a test that can fail—not a verdict that superposition or AI safety has been settled.
What happened
Goodfire’s research index dates Neural Networks Are Already Clean to 15 October 2026. The essay presents an informal working hypothesis about studying native neurons and circuits, with a technical companion still forthcoming.
Why it matters
An intelligible label is a research starting point. Evaluation teams should ask whether it predicts unseen activations and survives counterexamples before using interpretability as assurance.
Goodfire’s research index dates Nick Cammarata’s Neural Networks Are Already Clean to 15 October. The essay labels itself an informal working hypothesis and says a technical companion will provide more detail. It argues that studying a network’s own neurons and circuits may be more productive than assuming they first need to be untangled.
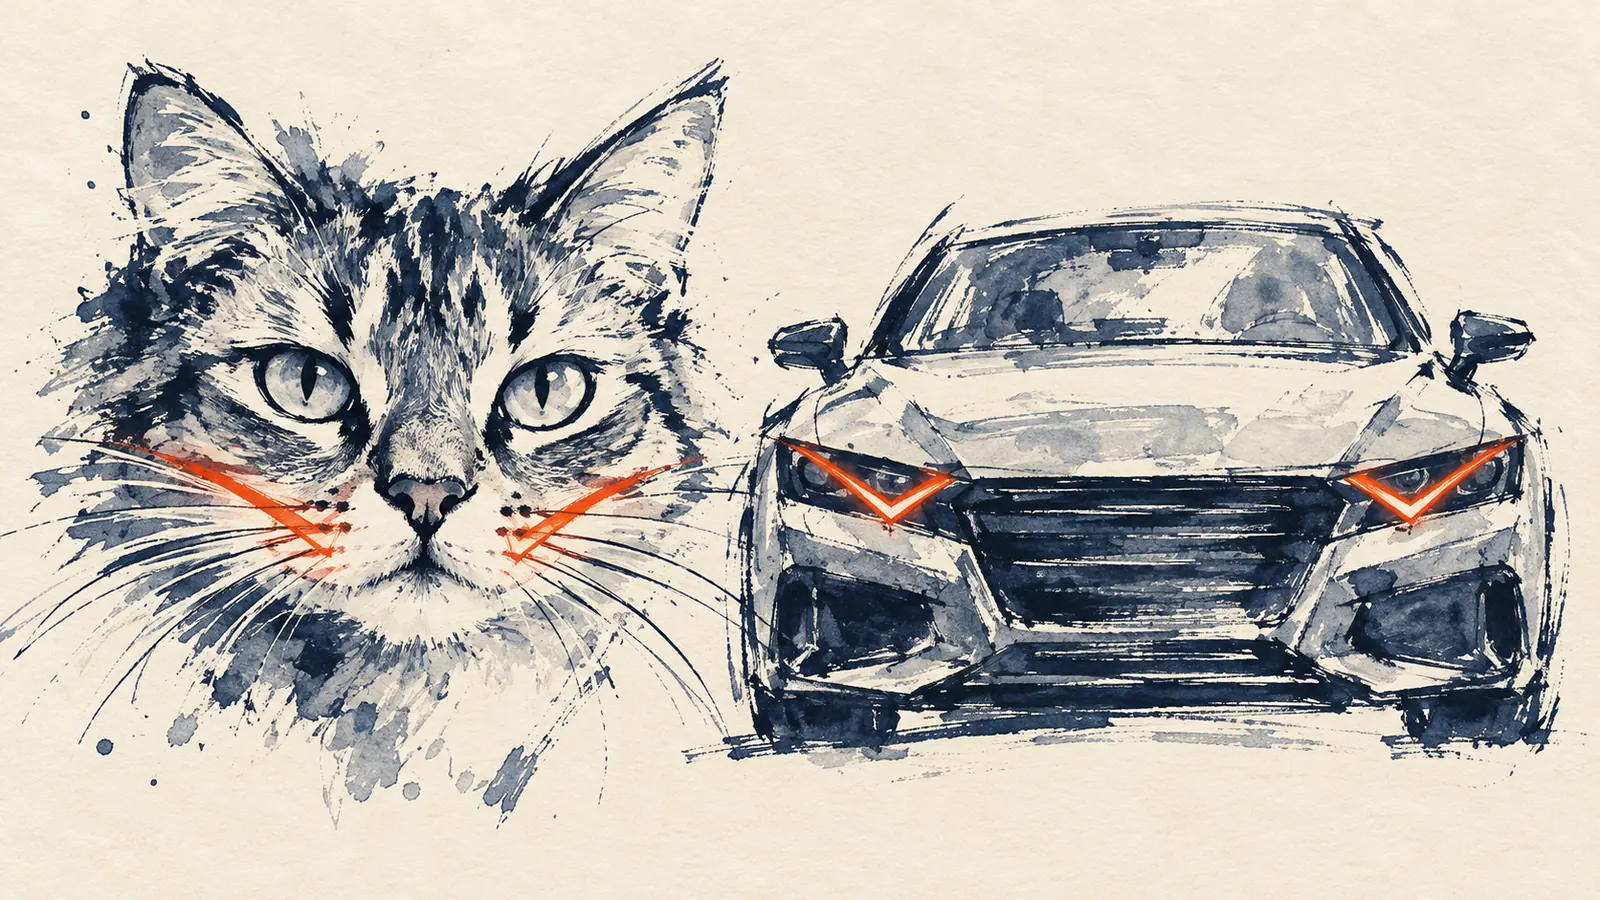
One concrete example revisits a neuron that responds to cat faces and car fronts. Cammarata interprets it as a shared pointed, V-shaped feature rather than an arbitrary combination of unrelated concepts. The larger proposal concerns how apparent mixtures arise and how to investigate them. It should not become a claim that every neuron is understood, that model behaviour is controlled, or that safety follows from a readable description.
A label should make a risky prediction
For a small replication exercise, take one proposed native-neuron explanation and write down what would disprove it. Predeclare examples expected to activate the neuron and near misses expected not to. Keep these apart from the observations used to invent the label. Then inspect held-out activations without revising the explanation to fit each surprise.
This is an editorial research-design proposal, not a result measured for this article. Record the model checkpoint, layer and neuron, sign regime, activation threshold, sampling frame and all rejected explanations. A positive and a negative response can carry different information; a memorable visualisation alone is not a complete account of the mechanism.
Preserve the strongest contrary distinction
The Toy Models of Superposition abstract describes a constructed setting where sparse features are stored in superposition and polysemanticity can be understood. That is primary experimental context from a different research group, not a replication of the new essay. Cammarata’s argument does not invalidate the existence of those toy-model results or settle whether representations contain more features than dimensions.
The uncertainty is about how far an explanation transfers across models, depths, weak activations and mechanisms. Selecting neurons with appealing examples can make explanations look easier than they are. A useful replication therefore reports the sampling rule and failures, not only a gallery of successes. The essay itself warns that cleanliness percentages depend on thresholds and what counts as one function; this article does not turn them into a population estimate.
The Skills Atlas entry on mechanistic interpretability is the relevant capability context: following mechanisms is different from simply scoring output quality. The new hypothesis warrants practice in constructing and breaking an explanation, not an automatic rewrite of that skill or a procurement claim about safe models.
The next decision is a bounded, independently repeatable falsification exercise. If the explanation fails, retain the counterexample. If it survives, treat it as evidence about that mechanism under that test—not a certificate for the whole network.