Expert data is a labour and provenance system, not a finished asset
Snorkel AI’s new funding highlights demand for expert-authored datasets and reinforcement-learning environments. Buyers still need to see who exercised judgment, how rubrics changed and where automated quality checks failed.
What happened
Reuters reported that Snorkel AI raised $350 million at a $3.5 billion valuation as its data-as-a-service business supplies expert-built datasets and reinforcement-learning environments for complex AI work.
Why it matters
When expert judgment becomes a purchased data product, procurement must govern contributor qualifications, instructions, compensation, disagreement, automation and version history—not just inspect a delivery file.
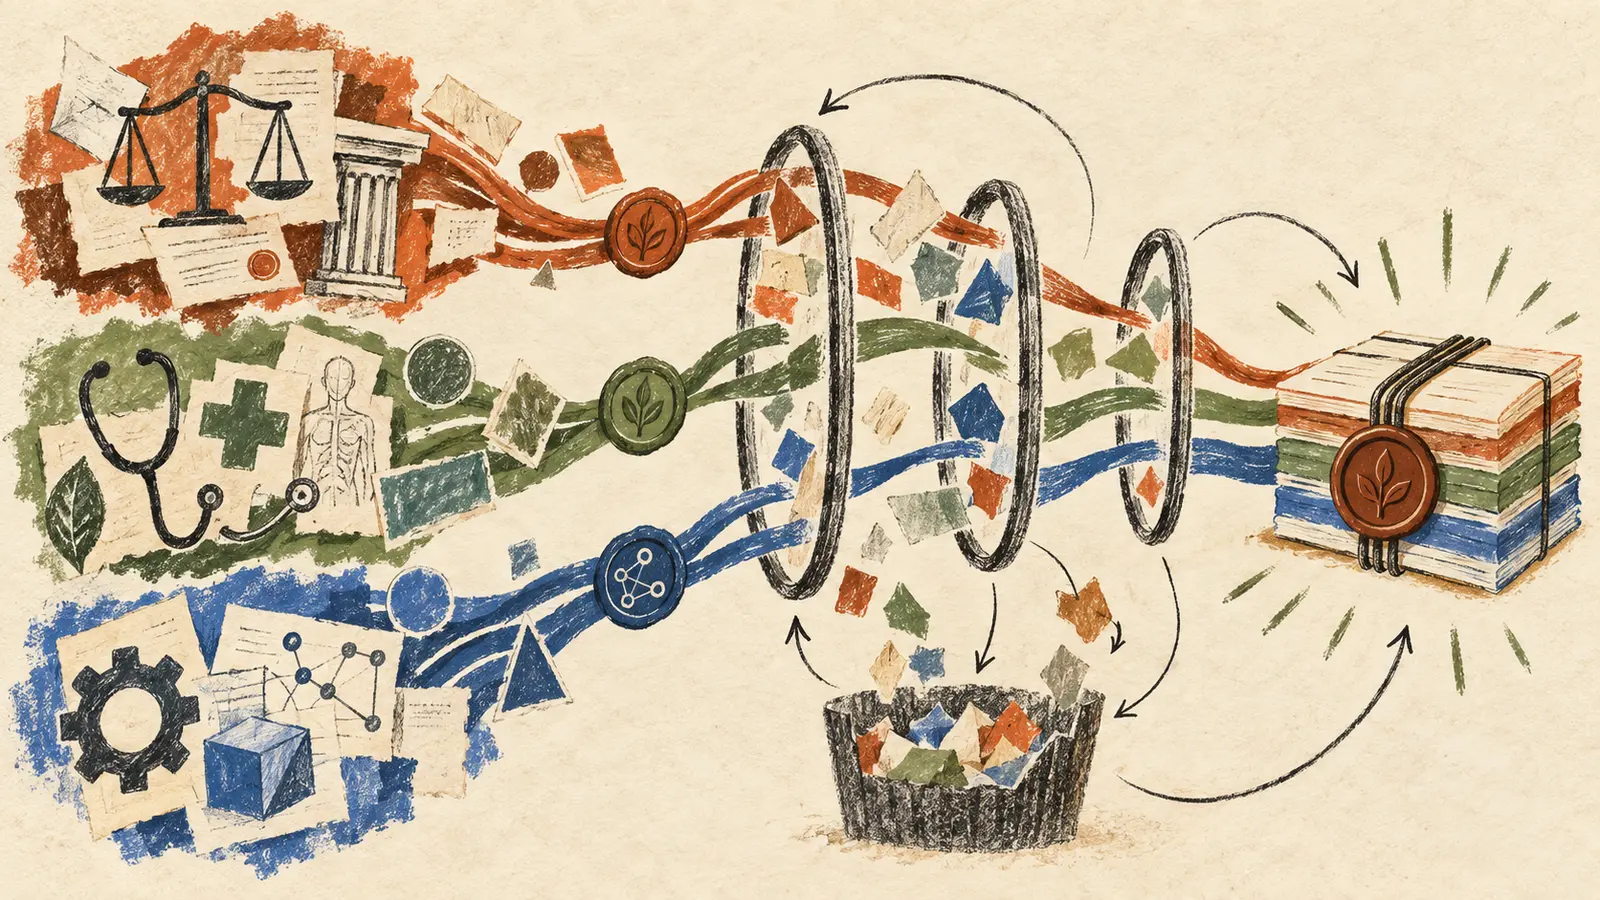
Reuters reported on 22 September that Snorkel AI raised $350 million at a $3.5 billion valuation. The company told Reuters that its annualised revenue run-rate had passed $350 million, driven by a data-as-a-service business supplying finished datasets and reinforcement-learning environments. Experts in coding, law and medicine reportedly design scenarios, tasks and grading rubrics while software automates part of quality assurance. Snorkel’s own description says it builds expert-authored datasets, evaluations and environments for frontier models.
The commercial signal is strong: difficult AI systems increasingly depend on structured human judgment, not only more raw text. Yet “expert data” can sound like a finished commodity when it is actually a production process. A rubric encodes assumptions about what counts as a correct answer, which harms matter, how ambiguity is resolved and when a task should be rejected. Those choices remain material even when software accelerates labelling or quality checks.
Buy the judgment chain, not only the dataset
A buyer should require a provenance record for every material slice. It should state the contributor qualification, task instructions, jurisdiction or domain context, compensation model, conflict rules, sampling method, automated assistance and review path. Changes to a rubric or simulated environment need versions and reasons. Where contributors disagree, the record should preserve the disagreement and adjudication instead of flattening it into one unexplained label.
Automated quality assurance also needs its own test. A model that proposes labels or flags outliers can reduce repetitive work, but it may standardise the same error across thousands of examples. Measure false acceptance, false rejection and subgroup disagreement on a blind expert sample. Keep some items outside the automation loop so the control is not evaluated by the system it is meant to check.
Treat workforce design as part of data quality
The operating model affects the evidence. Short tasks, unstable access, opaque rejection and incentives tied only to throughput can discourage experts from documenting uncertainty. Procurement should therefore ask how contributors are briefed, paid, appealed and protected when working with sensitive material. These questions are not separate from technical quality: they determine whether difficult cases are surfaced or silently normalised.
Business Insider reported in September 2025 that Snorkel cut about 13% of its workforce while shifting towards data as a service. That earlier restructuring does not contradict the later funding or revenue claims, but it is useful counterevidence against treating valuation growth as a simple measure of stable employment or mature operations. Business-model change can create value while redistributing work and risk.
For model teams, the acceptance test should link each training or evaluation result back to data and rubric versions. For legal and procurement teams, contracts should cover contributor rights, confidentiality, permitted automation, audit access and deletion. For workforce leaders, the question is whether scarce experts are building reusable judgment systems or performing invisible piecework.
Acceptance sampling should be planned before delivery. Define strata by domain, difficulty, contributor group and known failure mode, then draw a blind sample large enough to expose material disagreements. Have a second qualified reviewer reproduce the judgment without seeing the original label. Where disagreement persists, record whether it reflects ambiguous instructions, legitimate professional variation or an error. Report both the adjudicated label and the disagreement rate. A buyer can then decide whether the dataset is suitable for training, evaluation, monitoring or only exploratory use rather than treating all rows as equally authoritative.
The immediate decision is not whether expert data matters; it plainly does. It is whether the buyer can reconstruct how the judgment was produced and challenge it when the model fails. Without that chain, a polished dataset remains an opaque dependency.